xterm.js
Tested Software version 6.1.0-beta.302 on Linux. The xterm.js variant tested is the one shipped with Visual Studio Code’s integrated terminal. The homepage URL of this terminal is https://code.visualstudio.com/docs/terminal/basics. Full results available at ucs-detect repository path data/vscodeterminal.yaml.
xterm.js is a terminal multiplexer. These tests were executed in host terminal :ref:`ghostty. The homepage URL of this host terminal is https://ghostty.org/.
Score Breakdown
Detailed breakdown of how scores are calculated for xterm.js:
# |
Score Type |
Raw Score |
Final Scaled Score |
|---|---|---|---|
1 |
29.25% |
11.8% |
|
2 |
99.95% |
99.9% |
|
3 |
0.69% |
0.7% |
|
4 |
92.15% |
92.1% |
|
5 |
50.00% |
50.0% |
|
6 |
0.00% |
(excluded) |
|
7 |
0.00% |
0.0% |
|
8 |
100.00% |
100.0% |
|
9 |
100.00% |
100.0% |
|
10 |
47.22% |
47.2% |
|
11 |
0% |
0.0% |
|
12 |
N/A |
N/A |
Score Comparison Plot:
The following plot shows how this terminal’s scores compare to all other terminals tested.
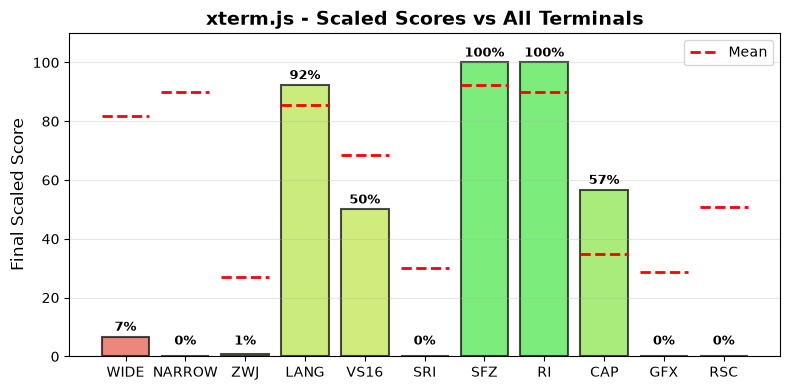
Scaled scores comparison across all metrics (normalized 0-100%)
Final Scaled Score Calculation:
Raw Final Score: 55.42% (weighted average: WIDE + NARROW + ZWJ + LANG + VS16 + 0.33 * SRI + 0.33 * SFZ + RI + CAP + 0.5 * GFX) the categorized ‘average’ absolute support level of this terminal.
Note
RSC (Resources) is a composite CPU, memory, and runtime score, displayed for comparison but excluded from the final score FEAT (Features) is the fraction of notable features supported. GFX (Graphics) scores 100% for modern protocols (iTerm2, Kitty), 50% for legacy only (Sixel, ReGIS), 0% for none.
Final Scaled Score: 26.4% (normalized across all terminals tested). Final Scaled scores are normalized (0-100%) relative to all terminals tested
WIDE Score Details:
Wide character support calculation:
Total successful contested codepoints: 148
Total contested codepoints tested: 506
Formula: 148 / 506
Result: 29.25%
NARROW Score Details:
Narrow character support calculation:
Total successful contested codepoints: 5592
Total contested codepoints tested: 5595
Formula: 5592 / 5595
Result: 99.95%
ZWJ Score Details:
Emoji ZWJ (Zero-Width Joiner) support calculation:
Total successful sequences: 10
Total sequences tested: 1445
Formula: 10 / 1445
Result: 0.69%
VS16 Score Details:
Variation Selector-16 support calculation:
Errors: 213 of 426 codepoints tested
Success rate: 50.0%
Formula: 50.0 / 100
Result: 50.00%
Variation Selector-15 support:
Note
Interpretation of VS-15 is contested. Its width behavior is not consistently implemented across terminals; this measurement is informational and excluded from final scoring.
Variation Selector-15 support calculation:
Errors: 158 of 158 codepoints tested
Success rate: 0.0%
Formula: 0.0 / 100
Result: 0.00%
SRI Score Details:
Standalone Regional Indicator support calculation:
Total successful codepoints: 0
Total codepoints tested: 26
Formula: 0 / 26
Result: 0.00%
SFZ Score Details:
Standalone Fitzpatrick skin tone modifier support calculation:
Total successful codepoints: 5
Total codepoints tested: 5
Formula: 5 / 5
Result: 100.00%
RI Score Details:
Regional Indicator flag sequence support calculation:
Total successful sequences: 262
Total sequences tested: 262
Formula: 262 / 262
Result: 100.00%
Features Score Details:
Notable terminal features (8.5 / 18):
XTGETTCAP: no
Tofu Detection: no
OSC 52 Clipboard: no
Truecolor Detection: partial
Raw score: 47.22%
Graphics Score Details:
Graphics protocol support (0%):
Sixel: no
ReGIS: no
iTerm2: no
Kitty: no
Scoring: 100% for modern (iTerm2/Kitty), 50% for legacy only (Sixel/ReGIS), 0% for none
Resource Score Details:
Resource profiling data not available.
LANG Score Details (Geometric Mean):
Geometric mean calculation:
Formula: (p₁ × p₂ × … × pₙ)^(1/n) where n = 85 contested languages
About geometric mean
Result: 92.15%
Wide character support
Wide character support of xterm.js is 97.0% (1341 errors of 44568 codepoints tested).
Sequence of a WIDE character, from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\U00019044’ |
Cn |
2 |
na |
Total codepoints: 1
Shell test using printf(1),
'|'should align in output:$ printf "\xf0\x99\x81\x84|\\n12|\\n" | 12|
python wcwidth.wcswidth() measures width 2, while xterm.js measures width 1.
Narrow character support
Narrow character support of xterm.js is 100.0% (3 errors of 36254 codepoints tested).
Sequence of a NARROW character, from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\U0001f93b’ |
So |
1 |
MODERN PENTATHLON |
Total codepoints: 1
Shell test using printf(1),
'|'should align in output:$ printf "\xf0\x9f\xa4\xbb|\\n1|\\n" 🤻| 1|
python wcwidth.wcswidth() measures width 1, while xterm.js measures width 2.
Emoji ZWJ support
Compatibility of xterm.js with the Unicode Emoji ZWJ sequence table is 0.7% (1435 errors of 1445 sequences tested).
Sequence of an Emoji ZWJ Sequence, from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\U0001f3c3’ |
So |
2 |
RUNNER |
|
2 |
‘\U0001f3fe’ |
Sk |
2 |
EMOJI MODIFIER FITZPATRICK TYPE-5 |
|
3 |
‘\u200d’ |
Cf |
0 |
ZERO WIDTH JOINER |
|
4 |
‘\u2640’ |
So |
1 |
FEMALE SIGN |
|
5 |
‘\ufe0f’ |
Mn |
0 |
VARIATION SELECTOR-16 |
|
6 |
‘\u200d’ |
Cf |
0 |
ZERO WIDTH JOINER |
|
7 |
‘\u27a1’ |
So |
1 |
BLACK RIGHTWARDS ARROW |
|
8 |
‘\ufe0f’ |
Mn |
0 |
VARIATION SELECTOR-16 |
Total codepoints: 8
Shell test using printf(1),
'|'should align in output:$ printf "\xf0\x9f\x8f\x83\xf0\x9f\x8f\xbe\xe2\x80\x8d\xe2\x99\x80\xef\xb8\x8f\xe2\x80\x8d\xe2\x9e\xa1\xef\xb8\x8f|\\n12|\\n" 🏃🏾♀️➡️| 12|
python wcwidth.wcswidth() measures width 2, while xterm.js measures width 6.
Variation Selector-16 support
Emoji VS-16 results for xterm.js is 213 errors out of 426 total codepoints tested, 50.0% success. Sequence of a NARROW Emoji made WIDE by Variation Selector-16, from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\u2733’ |
So |
1 |
EIGHT SPOKED ASTERISK |
|
2 |
‘\ufe0f’ |
Mn |
0 |
VARIATION SELECTOR-16 |
Total codepoints: 2
Shell test using printf(1),
'|'should align in output:$ printf "\xe2\x9c\xb3\xef\xb8\x8f|\\n12|\\n" ✳️| 12|
python wcwidth.wcswidth() measures width 2, while xterm.js measures width 1.
Variation Selector-15 support
Emoji VS-15 results for xterm.js is 158 errors out of 158 total codepoints tested, 0.0% success. Sequence of a WIDE Emoji made NARROW by Variation Selector-15, from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\U0001f3ae’ |
So |
2 |
VIDEO GAME |
|
2 |
‘\ufe0e’ |
Mn |
0 |
VARIATION SELECTOR-15 |
Total codepoints: 2
Shell test using printf(1),
'|'should align in output:$ printf "\xf0\x9f\x8e\xae\xef\xb8\x8e|\\n1|\\n" 🎮︎| 1|
python wcwidth.wcswidth() measures width 1, while xterm.js measures width 2.
Standalone Regional Indicator support
Standalone Regional Indicator support of xterm.js is 0.0% (26 errors of 26 codepoints tested).
Sequence of a standalone Regional Indicator, from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\U0001f1f3’ |
So |
2 |
REGIONAL INDICATOR SYMBOL LETTER N |
Total codepoints: 1
Shell test using printf(1),
'|'should align in output:$ printf "\xf0\x9f\x87\xb3|\\n12|\\n" 🇳| 12|
python wcwidth.wcswidth() measures width 2, while xterm.js measures width 1.
Standalone Fitzpatrick modifier support
Standalone Fitzpatrick skin tone modifier support of xterm.js is 100.0% (0 errors of 5 codepoints tested).
Regional Indicator flag sequence support
Regional Indicator flag sequence support of xterm.js is 100.0% (0 errors of 262 sequences tested).
Graphics Protocol Support
xterm.js does not report support for any graphics protocols.
Note: Must be enabled with "terminal.integrated.enableImages": true.
Detection Methods:
Sixel and ReGIS: Not detected via the Device Attributes (DA1) query
CSI c(\x1b[c). Sixel indicator (4): not present, ReGIS indicator (3): not present.Kitty graphics: Not detected by sending a Kitty graphics query and checking for an
OKresponse.iTerm2 inline images: Not detected by drawing a 1x1 transparent image,
OSC 1337 ; File=inline=1, and checking that the cursor advanced a single column.iTerm2 capabilities: Not detected via the
OSC 1337 ; Capabilitiesquery, which does not describe image support, and does not contribute to this score.
Device Attributes
Raw response:
'\x1b[?1;2c'Service class: 1 (VT100)
Detected Extensions:
Code
Description
2
Printer port
Language Support
The following 98 languages were tested with 100% success:
(Jinan), (Yeonbyeon), Aja, Amarakaeri, Arabic, Standard, Assyrian Neo-Aramaic, Baatonum, Bamun, Belanda Viri, Bora, Catalan (2), Chickasaw, Chinantec, Chiltepec, Chinese, Gan, Chinese, Hakka, Chinese, Jinyu, Chinese, Mandarin (Beijing), Chinese, Mandarin (Guiyang), Chinese, Mandarin (Harbin), Chinese, Mandarin (Nanjing), Chinese, Mandarin (Simplified), Chinese, Mandarin (Tianjin), Chinese, Mandarin (Traditional), Chinese, Min Nan, Chinese, Wu, Chinese, Xiang, Chinese, Yue, Colorado, Dagaare, Southern, Dangme, Dari, Dendi, Dinka, Northeastern, Ditammari, Dzongkha, Evenki, Farsi, Western, Fon, French (Welche), Fur, Ga, Gen, Gilyak, Gumuz, Japanese, Japanese (Osaka), Japanese (Tokyo), Kabyle, Korean, Lamnso’, Lao, Lingala (tones), Maldivian, Maori (2), Mazahua Central, Mirandese, Mixtec, Metlatónoc, Mongolian, Halh (Mongolian), Mòoré, Nanai, Navajo, Nuosu, Orok, Otomi, Mezquital, Panjabi, Eastern, Panjabi, Western, Pashto, Northern, Picard, Pular (Adlam), Saint Lucian Creole French, Secoya, Seraiki, Shan, Shipibo-Conibo, Sinhala, Siona, South Azerbaijani, Tagalog (Tagalog), Tai Dam, Tamazight, Central Atlas, Tamil, Tamil (Sri Lanka), Tem, Thai, Thai (2), Tibetan, Central, Ticuna, Uduk, Urdu, Urdu (2), Veps, Vietnamese, Vietnamese (Han nom), Waama, Yaneshaʼ, Yiddish, Eastern, Yoruba, Éwé.
The following 20 languages are not fully supported:
lang |
n_errors |
n_total |
pct_success |
|---|---|---|---|
321 |
530 |
39.4% |
|
145 |
493 |
70.6% |
|
247 |
844 |
70.7% |
|
96 |
385 |
75.1% |
|
86 |
391 |
78.0% |
|
82 |
390 |
79.0% |
|
61 |
293 |
79.2% |
|
90 |
443 |
79.7% |
|
71 |
357 |
80.1% |
|
69 |
352 |
80.4% |
|
74 |
419 |
82.3% |
|
11 |
70 |
84.3% |
|
50 |
343 |
85.4% |
|
43 |
314 |
86.3% |
|
41 |
313 |
86.9% |
|
42 |
384 |
89.1% |
|
14 |
287 |
95.1% |
|
13 |
267 |
95.1% |
|
10 |
268 |
96.3% |
|
7 |
332 |
97.9% |
Javanese (Javanese)
Sequence of language Javanese (Javanese) from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\ua98f’ |
Lo |
1 |
JAVANESE LETTER KA |
|
2 |
‘\ua9ba’ |
Mc |
0 |
JAVANESE VOWEL SIGN TALING |
|
3 |
‘\ua9b4’ |
Mc |
0 |
JAVANESE VOWEL SIGN TARUNG |
Total codepoints: 3
Shell test using printf(1),
'|'should align in output:$ printf "\xea\xa6\x8f\xea\xa6\xba\xea\xa6\xb4|\\n12|\\n" ꦏꦺꦴ| 12|
python wcwidth.wcswidth() measures width 2, while xterm.js measures width 3.
Sanskrit
Sequence of language Sanskrit from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\u0915’ |
Lo |
1 |
DEVANAGARI LETTER KA |
|
2 |
‘\u094d’ |
Mn |
0 |
DEVANAGARI SIGN VIRAMA |
|
3 |
‘\u0924’ |
Lo |
1 |
DEVANAGARI LETTER TA |
|
4 |
‘\u093f’ |
Mc |
0 |
DEVANAGARI VOWEL SIGN I |
Total codepoints: 4
Shell test using printf(1),
'|'should align in output:$ printf "\xe0\xa4\x95\xe0\xa5\x8d\xe0\xa4\xa4\xe0\xa4\xbf|\\n12|\\n" क्ति| 12|
Malayalam
Sequence of language Malayalam from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\u0d15’ |
Lo |
1 |
MALAYALAM LETTER KA |
|
2 |
‘\u0d4d’ |
Mn |
0 |
MALAYALAM SIGN VIRAMA |
|
3 |
‘\u0d15’ |
Lo |
1 |
MALAYALAM LETTER KA |
|
4 |
‘\u0d3e’ |
Mc |
0 |
MALAYALAM VOWEL SIGN AA |
Total codepoints: 4
Shell test using printf(1),
'|'should align in output:$ printf "\xe0\xb4\x95\xe0\xb5\x8d\xe0\xb4\x95\xe0\xb4\xbe|\\n12|\\n" ക്കാ| 12|
python wcwidth.wcswidth() measures width 2, while xterm.js measures width 3.
Bengali
Sequence of language Bengali from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\u0995’ |
Lo |
1 |
BENGALI LETTER KA |
|
2 |
‘\u09bf’ |
Mc |
0 |
BENGALI VOWEL SIGN I |
|
3 |
‘\u0982’ |
Mc |
0 |
BENGALI SIGN ANUSVARA |
Total codepoints: 3
Shell test using printf(1),
'|'should align in output:$ printf "\xe0\xa6\x95\xe0\xa6\xbf\xe0\xa6\x82|\\n12|\\n" কিং| 12|
python wcwidth.wcswidth() measures width 2, while xterm.js measures width 3.
Marathi
Sequence of language Marathi from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\u0915’ |
Lo |
1 |
DEVANAGARI LETTER KA |
|
2 |
‘\u094d’ |
Mn |
0 |
DEVANAGARI SIGN VIRAMA |
|
3 |
‘\u0924’ |
Lo |
1 |
DEVANAGARI LETTER TA |
|
4 |
‘\u093f’ |
Mc |
0 |
DEVANAGARI VOWEL SIGN I |
Total codepoints: 4
Shell test using printf(1),
'|'should align in output:$ printf "\xe0\xa4\x95\xe0\xa5\x8d\xe0\xa4\xa4\xe0\xa4\xbf|\\n12|\\n" क्ति| 12|
Hindi
Sequence of language Hindi from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\u0915’ |
Lo |
1 |
DEVANAGARI LETTER KA |
|
2 |
‘\u094d’ |
Mn |
0 |
DEVANAGARI SIGN VIRAMA |
|
3 |
‘\u0924’ |
Lo |
1 |
DEVANAGARI LETTER TA |
|
4 |
‘\u093f’ |
Mc |
0 |
DEVANAGARI VOWEL SIGN I |
Total codepoints: 4
Shell test using printf(1),
'|'should align in output:$ printf "\xe0\xa4\x95\xe0\xa5\x8d\xe0\xa4\xa4\xe0\xa4\xbf|\\n12|\\n" क्ति| 12|
Sanskrit (Grantha)
Sequence of language Sanskrit (Grantha) from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\U00011315’ |
Lo |
1 |
GRANTHA LETTER KA |
|
2 |
‘\U0001133e’ |
Mc |
0 |
GRANTHA VOWEL SIGN AA |
|
3 |
‘\U00011302’ |
Mc |
0 |
GRANTHA SIGN ANUSVARA |
Total codepoints: 3
Shell test using printf(1),
'|'should align in output:$ printf "\xf0\x91\x8c\x95\xf0\x91\x8c\xbe\xf0\x91\x8c\x82|\\n12|\\n" 𑌕𑌾𑌂| 12|
python wcwidth.wcswidth() measures width 2, while xterm.js measures width 3.
Khmer, Central
Sequence of language Khmer, Central from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\u1780’ |
Lo |
1 |
KHMER LETTER KA |
|
2 |
‘\u17d2’ |
Mn |
0 |
KHMER SIGN COENG |
|
3 |
‘\u178a’ |
Lo |
1 |
KHMER LETTER DA |
|
4 |
‘\u17c5’ |
Mc |
0 |
KHMER VOWEL SIGN AU |
Total codepoints: 4
Shell test using printf(1),
'|'should align in output:$ printf "\xe1\x9e\x80\xe1\x9f\x92\xe1\x9e\x8a\xe1\x9f\x85|\\n12|\\n" ក្ដៅ| 12|
python wcwidth.wcswidth() measures width 2, while xterm.js measures width 3.
Maithili
Sequence of language Maithili from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\u0915’ |
Lo |
1 |
DEVANAGARI LETTER KA |
|
2 |
‘\u094d’ |
Mn |
0 |
DEVANAGARI SIGN VIRAMA |
|
3 |
‘\u0924’ |
Lo |
1 |
DEVANAGARI LETTER TA |
|
4 |
‘\u093f’ |
Mc |
0 |
DEVANAGARI VOWEL SIGN I |
Total codepoints: 4
Shell test using printf(1),
'|'should align in output:$ printf "\xe0\xa4\x95\xe0\xa5\x8d\xe0\xa4\xa4\xe0\xa4\xbf|\\n12|\\n" क्ति| 12|
Nepali
Sequence of language Nepali from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\u0915’ |
Lo |
1 |
DEVANAGARI LETTER KA |
|
2 |
‘\u094d’ |
Mn |
0 |
DEVANAGARI SIGN VIRAMA |
|
3 |
‘\u0924’ |
Lo |
1 |
DEVANAGARI LETTER TA |
|
4 |
‘\u093f’ |
Mc |
0 |
DEVANAGARI VOWEL SIGN I |
Total codepoints: 4
Shell test using printf(1),
'|'should align in output:$ printf "\xe0\xa4\x95\xe0\xa5\x8d\xe0\xa4\xa4\xe0\xa4\xbf|\\n12|\\n" क्ति| 12|
Khün
Sequence of language Khün from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\u1a20’ |
Lo |
1 |
TAI THAM LETTER HIGH KA |
|
2 |
‘\u1a6e’ |
Mc |
0 |
TAI THAM VOWEL SIGN E |
|
3 |
‘\u1a60’ |
Mn |
0 |
TAI THAM SIGN SAKOT |
|
4 |
‘\u1a2f’ |
Lo |
1 |
TAI THAM LETTER DA |
|
5 |
‘\u1a68’ |
Mn |
0 |
TAI THAM VOWEL SIGN UUE |
Total codepoints: 5
Shell test using printf(1),
'|'should align in output:$ printf "\xe1\xa8\xa0\xe1\xa9\xae\xe1\xa9\xa0\xe1\xa8\xaf\xe1\xa9\xa8|\\n12|\\n" ᨠᩮ᩠ᨯᩨ| 12|
python wcwidth.wcswidth() measures width 2, while xterm.js measures width 3.
Tamang, Eastern
Sequence of language Tamang, Eastern from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\u0915’ |
Lo |
1 |
DEVANAGARI LETTER KA |
|
2 |
‘\u094d’ |
Mn |
0 |
DEVANAGARI SIGN VIRAMA |
|
3 |
‘\u0924’ |
Lo |
1 |
DEVANAGARI LETTER TA |
|
4 |
‘\u093f’ |
Mc |
0 |
DEVANAGARI VOWEL SIGN I |
Total codepoints: 4
Shell test using printf(1),
'|'should align in output:$ printf "\xe0\xa4\x95\xe0\xa5\x8d\xe0\xa4\xa4\xe0\xa4\xbf|\\n12|\\n" क्ति| 12|
Gujarati
Sequence of language Gujarati from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\u0a95’ |
Lo |
1 |
GUJARATI LETTER KA |
|
2 |
‘\u0acd’ |
Mn |
0 |
GUJARATI SIGN VIRAMA |
|
3 |
‘\u0a95’ |
Lo |
1 |
GUJARATI LETTER KA |
|
4 |
‘\u0abe’ |
Mc |
0 |
GUJARATI VOWEL SIGN AA |
Total codepoints: 4
Shell test using printf(1),
'|'should align in output:$ printf "\xe0\xaa\x95\xe0\xab\x8d\xe0\xaa\x95\xe0\xaa\xbe|\\n12|\\n" ક્કા| 12|
python wcwidth.wcswidth() measures width 2, while xterm.js measures width 3.
Magahi
Sequence of language Magahi from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\u0915’ |
Lo |
1 |
DEVANAGARI LETTER KA |
|
2 |
‘\u094d’ |
Mn |
0 |
DEVANAGARI SIGN VIRAMA |
|
3 |
‘\u0924’ |
Lo |
1 |
DEVANAGARI LETTER TA |
|
4 |
‘\u093f’ |
Mc |
0 |
DEVANAGARI VOWEL SIGN I |
Total codepoints: 4
Shell test using printf(1),
'|'should align in output:$ printf "\xe0\xa4\x95\xe0\xa5\x8d\xe0\xa4\xa4\xe0\xa4\xbf|\\n12|\\n" क्ति| 12|
Bhojpuri
Sequence of language Bhojpuri from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\u0915’ |
Lo |
1 |
DEVANAGARI LETTER KA |
|
2 |
‘\u094d’ |
Mn |
0 |
DEVANAGARI SIGN VIRAMA |
|
3 |
‘\u0918’ |
Lo |
1 |
DEVANAGARI LETTER GHA |
|
4 |
‘\u094d’ |
Mn |
0 |
DEVANAGARI SIGN VIRAMA |
|
5 |
‘\u0918’ |
Lo |
1 |
DEVANAGARI LETTER GHA |
|
6 |
‘\u093f’ |
Mc |
0 |
DEVANAGARI VOWEL SIGN I |
|
7 |
‘\u094d’ |
Mn |
0 |
DEVANAGARI SIGN VIRAMA |
Total codepoints: 7
Shell test using printf(1),
'|'should align in output:$ printf "\xe0\xa4\x95\xe0\xa5\x8d\xe0\xa4\x98\xe0\xa5\x8d\xe0\xa4\x98\xe0\xa4\xbf\xe0\xa5\x8d|\\n12|\\n" क्घ्घि्| 12|
python wcwidth.wcswidth() measures width 2, while xterm.js measures width 4.
Telugu
Sequence of language Telugu from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\u0c15’ |
Lo |
1 |
TELUGU LETTER KA |
|
2 |
‘\u0c41’ |
Mc |
0 |
TELUGU VOWEL SIGN U |
|
3 |
‘\u0c02’ |
Mc |
0 |
TELUGU SIGN ANUSVARA |
Total codepoints: 3
Shell test using printf(1),
'|'should align in output:$ printf "\xe0\xb0\x95\xe0\xb1\x81\xe0\xb0\x82|\\n12|\\n" కుం| 12|
python wcwidth.wcswidth() measures width 2, while xterm.js measures width 3.
Kannada
Sequence of language Kannada from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\u0c95’ |
Lo |
1 |
KANNADA LETTER KA |
|
2 |
‘\u0cbe’ |
Mc |
0 |
KANNADA VOWEL SIGN AA |
|
3 |
‘\u0c82’ |
Mc |
0 |
KANNADA SIGN ANUSVARA |
Total codepoints: 3
Shell test using printf(1),
'|'should align in output:$ printf "\xe0\xb2\x95\xe0\xb2\xbe\xe0\xb2\x82|\\n12|\\n" ಕಾಂ| 12|
python wcwidth.wcswidth() measures width 2, while xterm.js measures width 3.
Chakma
Sequence of language Chakma from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\U00011107’ |
Lo |
1 |
CHAKMA LETTER KAA |
|
2 |
‘\U00011133’ |
Mn |
0 |
CHAKMA VIRAMA |
|
3 |
‘\U00011120’ |
Lo |
1 |
CHAKMA LETTER YYAA |
|
4 |
‘\U0001112c’ |
Mc |
0 |
CHAKMA VOWEL SIGN E |
Total codepoints: 4
Shell test using printf(1),
'|'should align in output:$ printf "\xf0\x91\x84\x87\xf0\x91\x84\xb3\xf0\x91\x84\xa0\xf0\x91\x84\xac|\\n12|\\n" 𑄇𑄳𑄠𑄬| 12|
python wcwidth.wcswidth() measures width 2, while xterm.js measures width 3.
Burmese
Sequence of language Burmese from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\u1000’ |
Lo |
1 |
MYANMAR LETTER KA |
|
2 |
‘\u103b’ |
Mc |
0 |
MYANMAR CONSONANT SIGN MEDIAL YA |
|
3 |
‘\u1031’ |
Mc |
0 |
MYANMAR VOWEL SIGN E |
Total codepoints: 3
Shell test using printf(1),
'|'should align in output:$ printf "\xe1\x80\x80\xe1\x80\xbb\xe1\x80\xb1|\\n12|\\n" ကျေ| 12|
python wcwidth.wcswidth() measures width 2, while xterm.js measures width 3.
Mon
Sequence of language Mon from midpoint of alignment failure records:
# |
Codepoint |
Python |
Category |
wcwidth |
Name |
|---|---|---|---|---|---|
1 |
‘\u1007’ |
Lo |
1 |
MYANMAR LETTER JA |
|
2 |
‘\u103c’ |
Mc |
0 |
MYANMAR CONSONANT SIGN MEDIAL RA |
|
3 |
‘\u1031’ |
Mc |
0 |
MYANMAR VOWEL SIGN E |
Total codepoints: 3
Shell test using printf(1),
'|'should align in output:$ printf "\xe1\x80\x87\xe1\x80\xbc\xe1\x80\xb1|\\n12|\\n" ဇြေ| 12|
python wcwidth.wcswidth() measures width 2, while xterm.js measures width 3.
DEC Private Modes Support
DEC private modes results for xterm.js: 4 changeable modes of 4 supported out of 8 total modes tested (50.0% support, 50.0% changeable).
Complete list of DEC private modes tested:
Mode |
Name |
Description |
Supported |
Changeable |
Enabled |
|---|---|---|---|---|---|
1004 |
FOCUS_IN_OUT_EVENTS |
Send FocusIn/FocusOut events |
Yes |
Yes |
No |
1006 |
MOUSE_EXTENDED_SGR |
Enable SGR Mouse Mode |
Yes |
Yes |
No |
2004 |
BRACKETED_PASTE |
Set bracketed paste mode |
Yes |
Yes |
No |
2026 |
SYNCHRONIZED_OUTPUT |
Synchronized Output |
Yes |
Yes |
No |
2027 |
GRAPHEME_CLUSTERING |
Grapheme Clustering |
No |
No |
No |
2031 |
COLOR_PALETTE_UPDATES |
Color palette updates |
No |
No |
No |
2048 |
IN_BAND_WINDOW_RESIZE |
In-Band Window Resize Notifications |
No |
No |
No |
5522 |
BRACKETED_PASTE_MIME |
Bracketed Paste MIME |
No |
No |
No |
Summary: 4 changeable, 4 not changeable.
Kitty Keyboard Protocol
xterm.js supports the Kitty keyboard protocol.
# |
Flag |
Key |
Supported |
|---|---|---|---|
1 |
Disambiguate escape codes |
|
Yes |
2 |
Report event types |
|
Yes |
3 |
Report alternate keys |
|
Yes |
4 |
Report all keys as escape codes |
|
Yes |
5 |
Report associated text |
|
Yes |
Detection is performed by enabling all progressive enhancement
modes by set (CSI = 31 ; 1 u) and re-querying with CSI ? u
to confirm which modes the terminal honors, before restoring its
original flags.
XTGETTCAP (Terminfo Capabilities)
xterm.js does not support the XTGETTCAP sequence.
Text Sizing Protocol (OSC 66)
xterm.js does not support the Text Sizing protocol.
Tofu Detection
A tofu is the □ U+25A1 WHITE SQUARE placeholder box drawn in place of
a codepoint the terminal’s font has no glyph for. Two protocols allow a
program to ask which codepoints may ‘tofu’: mintty’s Font
Glyph Coverage Enquiry and the Glyph Protocol implemented first by Rio.
xterm.js does not answer a font glyph coverage enquiry by either protocol, ‘tofus’ cannot be determined by automatic code.
Truecolor Support
xterm.js supports 24-bit truecolor, detectable via:
XTGETTCAP (RGB capability): no
DECRQSS (truecolor probe): no
COLORTERM: yes (truecolor)
Warning
COLORTERM is an environment variable, not a terminal query. It is not forwarded over SSH without SendEnv / AcceptEnv configuration, so detection via COLORTERM alone may be unreliable on remote hosts.
OSC 52 Clipboard Support
xterm.js does not advertise OSC 52 clipboard support via DA1 extension 52 or XTGETTCAP Ms.
DA1 extension 52: no
XTGETTCAP Ms: no
Terminal Identification
xterm.js is identified as xterm.js version 6.1.0-beta.302 (detected via XTVERSION).
XTVERSION (raw): xterm.js(6.1.0-beta.302)
XTVERSION: yes
XTGETTCAP TN: no
ENQ: no
TERM_PROGRAM: yes (vscode)
TERM: no (xterm-256color) (inherited from host terminal)
Reproduction
To reproduce these results for xterm.js, install and run ucs-detect with the following commands:
uvx ucs-detect --rerun data/vscodeterminal.yaml
Test Performance
Performance data for xterm.js is not available.